NexGen AI SRE Virtual Summit (US Edition)
AI is changing how engineering teams detect, investigate, and resolve production issues. Explore how AI SRE can move reliability operations from manual investigation to intelligent, automated response. Learn how teams can connect alerts, changes, workloads, and infrastructure signals to identify root causes faster. Discover practical approaches to autonomous troubleshooting, proactive reliability, and governed AI operations across cloud-native environments.
Date
3rd December 2026Time
11:00 AM ETExperts Speakers
6+Overview
From Incident Response to Autonomous Reliability
Modern cloud-native environments generate an enormous volume of alerts, changes, logs, events, and infrastructure signals. SRE teams often spend significant time connecting these signals, investigating incidents, and determining the right remediation path.
The NexGen AI SRE Virtual Summit (US Edition) will explore how AI can support and automate critical reliability workflows across Kubernetes and cloud-native environments. The discussions will focus on faster incident investigation, intelligent root-cause analysis, proactive reliability, and reducing operational toil.
The summit will explore how organizations can:
- Use AI to detect and investigate production incidents faster
- Correlate alerts, infrastructure changes, workloads, and application signals
- Accelerate root-cause analysis across complex Kubernetes environments
- Automate repetitive troubleshooting and remediation workflows
- Reduce alert noise and prioritize issues that require immediate attention
- Build proactive reliability practices that address issues before they become incidents
- Improve incident response through AI-powered investigation and guided remediation
- Give developers greater visibility into Kubernetes issues without requiring deep platform expertise
- Use change intelligence to identify risky changes before they impact production
- Improve CI/CD health and resolve pipeline issues before they disrupt releases
- Apply AI agents to production operations with appropriate governance and controls
- Measure and improve reliability outcomes while reducing operational toil
By bringing together SRE, DevOps, platform engineering, and cloud-native leaders, the summit will examine how organizations can build more responsive and increasingly autonomous reliability operations without losing visibility or control.
Why
Detect Faster. Investigate Smarter. Automate Reliability.
Here’s why you shouldn’t miss it:
Digital Sessions
Learn practical approaches to AI-powered incident investigation, Kubernetes troubleshooting, root-cause analysis, and autonomous reliability.
Digital Panel Discussions
Hear engineering leaders discuss alert fatigue, operational toil, AI-assisted remediation, proactive reliability, and production governance.
Digital Networking
Connect with SRE, DevOps, platform engineering, cloud infrastructure, and engineering leaders working to modernize production operations.
Virtual One-to-One Meetings
Exchange ideas with experts on AI SRE adoption, incident automation, Kubernetes reliability, and governed autonomous operations.
Our
Knowledge Sessions
Experience dynamic web panel discussions, live fireside chats, and interactive digital presentations that offer in-depth insights.
Industry Leaders
Connect virtually with industry leaders, decision-makers, and experts to explore emerging trends, share insights, and discover new strategies shaping the future.
Attendees
Join a distinguished group of senior executives and industry professionals for meaningful knowledge exchange and collaboration.
Our
- Moving From Manual Incident Investigation to AI-Assisted SRE
- Correlating Alerts, Changes, and Workload Signals to Find Root Cause
- Reducing MTTR Through Automated Investigation and Remediation
- Managing Kubernetes Incidents Across Complex Cloud-Native Environments
- Cutting Alert Noise Without Losing Critical Reliability Signals
- Using AI to Detect Risky Changes Before They Trigger Production Incidents
- Building Proactive Reliability Workflows Instead of Reactive Firefighting
- Empowering Developers to Troubleshoot Kubernetes Without Deep Platform Expertise
- Turning Runbooks and Operational Knowledge Into Automated Workflows
- Applying AI Agents to Incident Management and Production Operations
- Keeping Human Oversight in High-Risk Autonomous Remediation
- Measuring the Business and Engineering Impact of AI-Driven Reliability
Key Focus Areas
- AI Site Reliability Engineering
- Autonomous Operations
- Kubernetes Reliability
- Incident Management
- Root-Cause Analysis
- Alert Intelligence
- Proactive Reliability
- Change Intelligence
- AI-Powered Troubleshooting
- Agentic Workflows
- Production Governance
- Cloud-Native Operations

WHO SHOULD ATTEND?
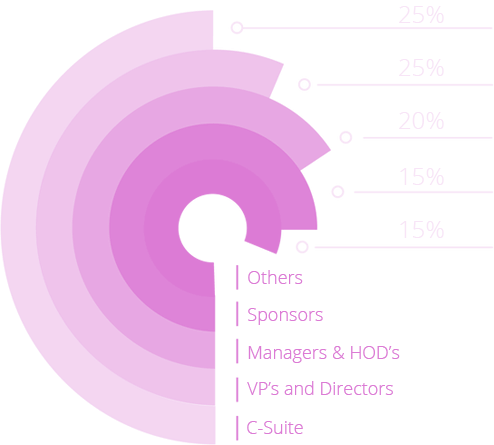
CXOs, VPs, Directors, Heads, Managers & Specialists in -
- Chief Technology Officers
- Chief Information Officers
- Heads of Site Reliability Engineering
- Heads of DevOps
- Heads of Platform Engineering
- SRE Directors
- DevOps Directors
- Platform Engineering Directors
- Cloud Infrastructure Directors
- Site Reliability Engineering Managers
- DevOps Engineering Managers
- Cloud Operations Leaders
Topics
AI SRE
Autonomous Incident Response
Kubernetes Troubleshooting
Root-Cause Analysis
Alert Management
Incident Automation
Proactive Reliability Engineering
Change Risk Management
AI Agents for IT Operations
Cloud-Native Reliability
Production Readiness
SRE Automation
Our
Banking & Financial Services
Insurance
Technology & SaaS
Healthcare
Retail & E-commerce
Manufacturing
Telecommunications
Automotive
Energy & Utilities
Media & Entertainment
Transportation & Logistics
Government
Speakers


Karen Mascarenhas
Manager, Demand Generation - Uniphore
Thank you for the great session. Reimagining Customer Experiences with Proactive Customer Care

Jennifer Mavaseh
Director of Business Development -Nastel Technologies, Inc.
It was a pleasure working with you on this webinar. AIOP’s for Businesses

Elise Dumolin
Field Marketing Manager -DACH -Nintex
Thank you so much for all ur support for the event. Expense Management for Businesses

Cameron
Regional Marketing Specialist, APAC - Akeneo
Thank you again for your assistance with hosting the event and I turned in for a brief period and was very happy with how smoothly things were running.. Digital Process Automation for Businesses
Frequently Asked Questions
Where will the event be held?
This is an online event. You do not have to travel to any specific location. You can participate from your convenient location. The virtual event is accessible from a computer, mobile and tablet devices.
How do I log in on the day of the virtual event?
Your login details will be sent to you via email before the event. Use them to access the online platform.
Can I invite my colleagues and friends to attend the virtual event?
Absolutely. We are counting on you to invite others! Help us spread the word. You can simply share the link to this page, and they can register at their convenience.
